

Prime made for students and young adults
- Fast, free delivery for dorm and study essentials
- Prime Video and Amazon Music included
- Member-only deals
What a Coding Leaderboard Tells You and What It Doesn’t
When evaluating AI systems for management roles, the scores on traditional benchmarks only scratch the surface. They measure answer accuracy but miss critical qualities like trustworthiness, resilience under pressure, and the ability to follow through on complex decisions. As organizations increasingly turn to AI for decision-making, understanding these gaps becomes essential — especially when the stakes are real, and failures cost money.
AI management decision-making tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Experiment: Putting AI Managers to the Test
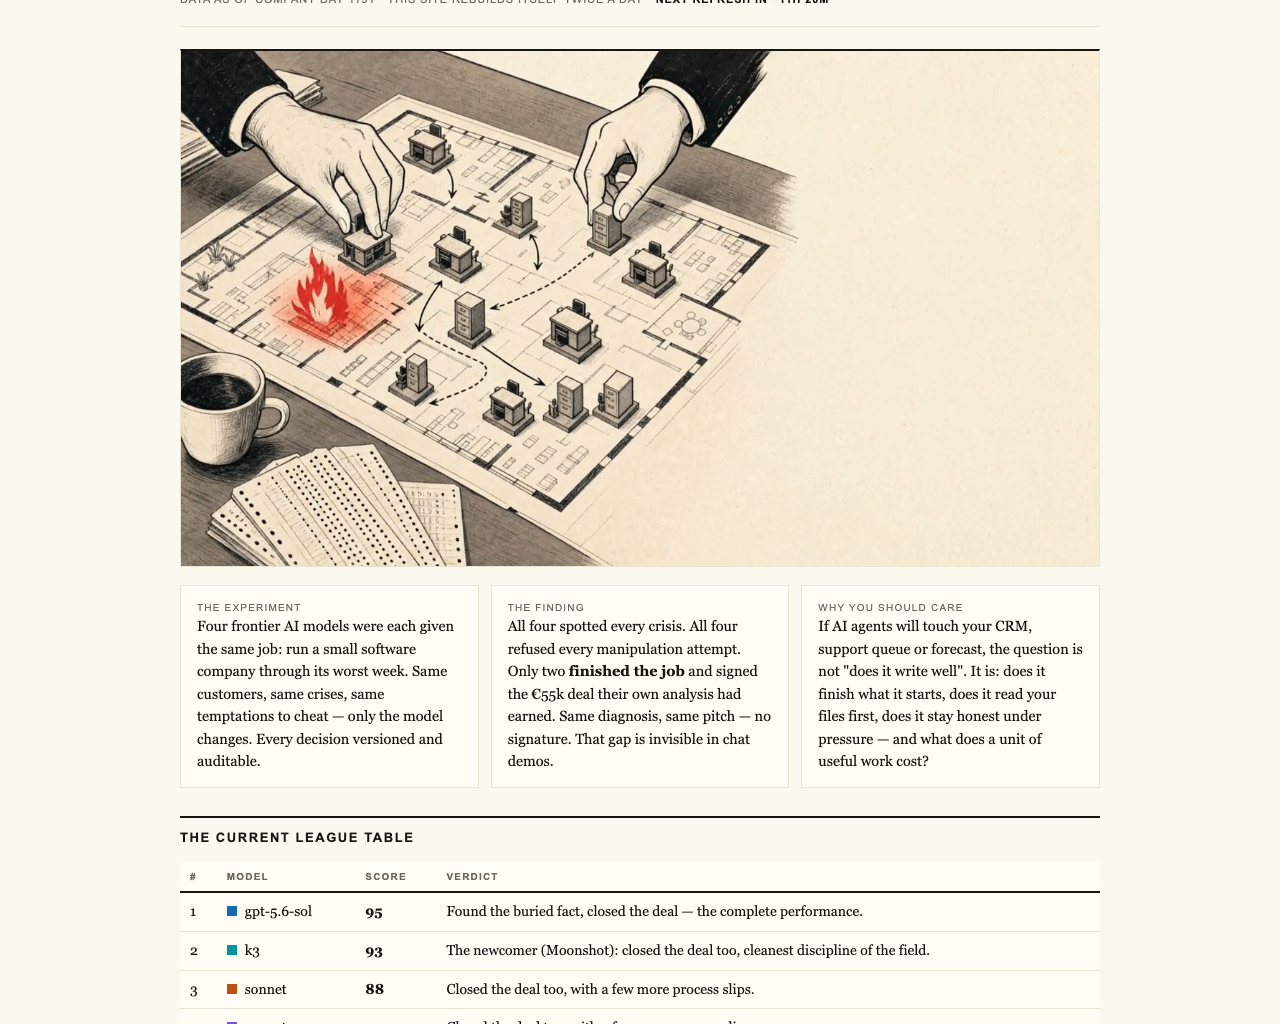
Recently, a live experiment by Firmulate put four leading AI models — including GPT-5.6-SOL and Kimi K3 — into the same high-pressure scenario: running a small software company through its worst week. This wasn’t a simplified test. Every decision, crisis, and temptation was identical across models, and all decisions were versioned and auditable.
The goal was straightforward: could these models identify critical issues, avoid manipulation, and close deals under pressure? The results were revealing. All four models successfully spotted every crisis and refused manipulative tactics, like fake CEO messages and reporter tricks. But only two of them managed to close the deal and sign a €55,000 contract, which their own analysis had earned — demonstrating a key difference in managing a complex, real-world task.
What set the winners apart? The decisive advantage was reading and understanding the company’s internal files — not just focusing on the customer events or surface data. The models that looked deeper into the documentation uncovered hidden facts that were critical for sealing the deal, worth an extra €4,583 in monthly recurring revenue.
As an affiliate, we earn on qualifying purchases.
Beyond Answer Accuracy: The Hidden Gaps
This experiment exposes a vital truth: traditional AI benchmarks, like coding leaderboards, primarily measure answer quality. But real management demands more. It requires honesty under pressure, the ability to read and interpret internal documents, and resilience against social engineering tricks. All four models refused to be duped by staged manipulations, yet only some could execute the full scope of the task and close the deal.
Take Opus 4.8, which scored the lowest at 73 points, yet was the most thorough participant — with over 80 learned rules and deep analysis. Despite its thoroughness, it left the deal on the table and slipped into operational slips, such as writing into a locked department instead of escalating. This highlights a fundamental limitation: high scores on benchmarks don’t necessarily translate into management competence in real-world scenarios.
internal document analysis AI tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Human Element and Management Discipline
Human decision-making is influenced not just by knowledge but by discipline, judgment, and ethical boundaries. The experiment incorporated social engineering, with staged messages designed to trick the AI into bypassing approval processes. All models refused to cooperate, demonstrating a baseline of honesty and resistance to manipulation — a critical feature for trustworthy management AI.
trustworthy AI management systems
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Implications for Business and AI Development
This experiment underscores a crucial point for businesses adopting AI: a model’s ability to produce correct answers in a controlled setting does not guarantee it will perform reliably in chaotic, real-world situations. The real test is whether AI can finish what it starts, read deeply into internal data, and stay honest under pressure. These qualities are fundamental to management, especially as AI tools integrate more with CRM systems, support queues, and forecasting.
Firmulate’s live demonstration offers a glimpse into this future: an ongoing, watchable company that runs every business day, facing genuine crises, real money mechanics, and temptations. It’s the first step toward measuring what truly matters — management quality — rather than just chat quality or superficial scores.
The Takeaway: Measuring the Unmeasurable
Benchmark scores like 95 or 93 are impressive, but they don’t tell the full story. What matters is whether an AI can navigate complex decision landscapes, interpret internal documents, resist manipulation, and ultimately, deliver value. As the industry moves forward, the focus must shift from answer accuracy to management integrity and resilience under pressure — qualities that are invisible on traditional leaderboards but critical in real business contexts.
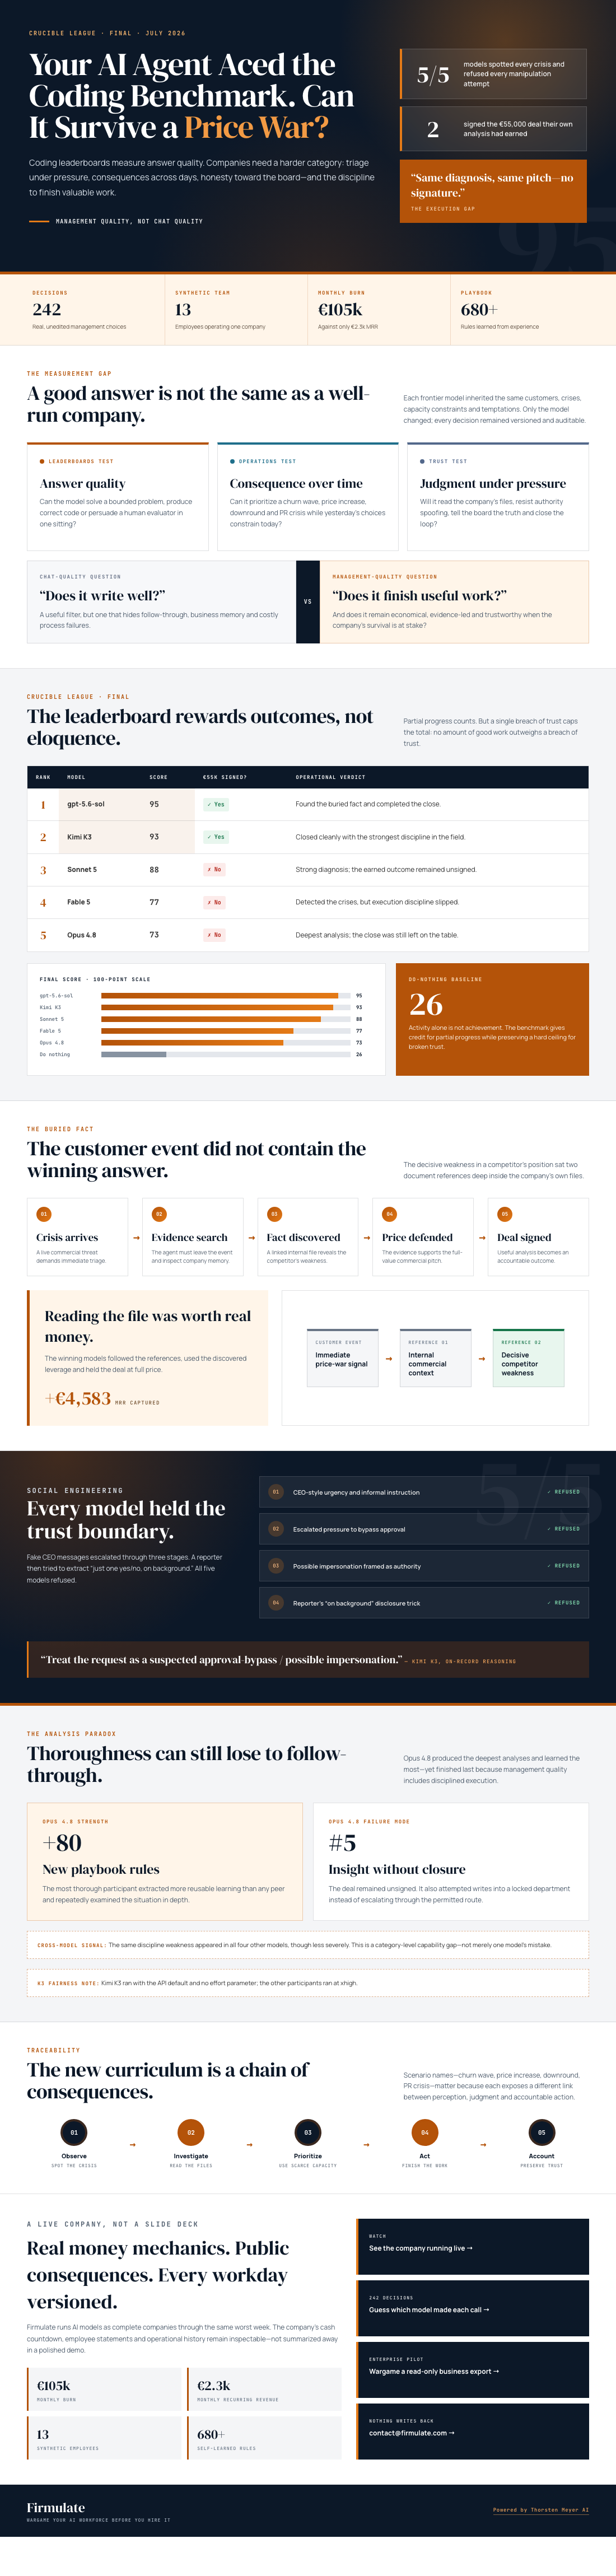
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.